Topic Hub
Strix Halo Mini PCs for Local AI
Strix Halo is AMD's Ryzen AI Max+ 395: a 16-core Zen 5 APU with a Radeon 8060S iGPU and 128GB of LPDDR5X unified memory, up to 96GB of it allocatable as VRAM. That's enough to hold 70B-class models no 24–32GB consumer GPU can fit. The trade-off is bandwidth — real-world ~215–273 GB/s depending on the box — so dense 70B runs at single-digit tokens/sec while MoE models fly. Buy these for capacity, not raw speed.
Top Picks
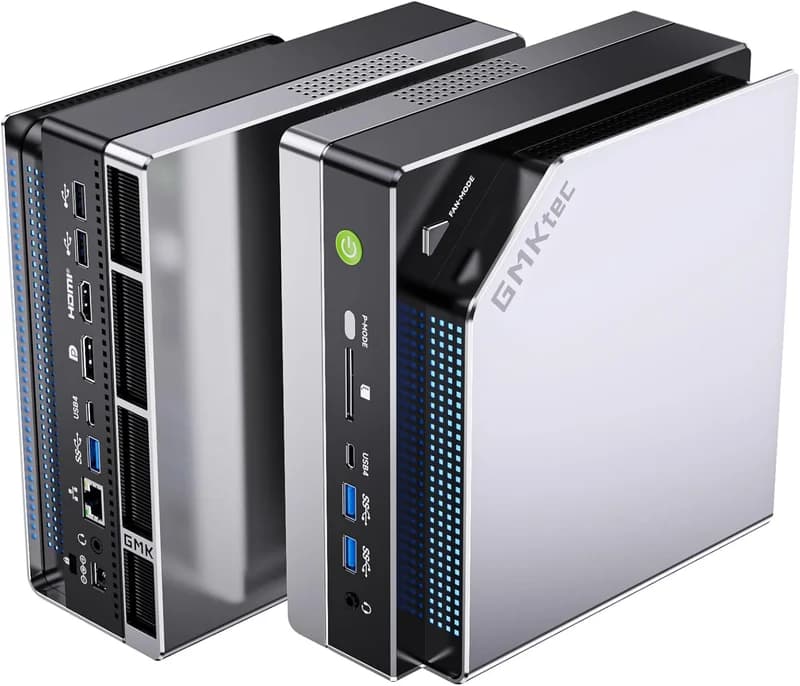
GMKtec EVO-X2 (Ryzen AI Max+ 395, 128GB)
$3,649
- APU: AMD Ryzen AI Max+ 395 (16C/32T, Zen 5)
- GPU: Radeon 8060S (40 CU, RDNA 3.5)
- NPU: 50 TOPS (XDNA 2)
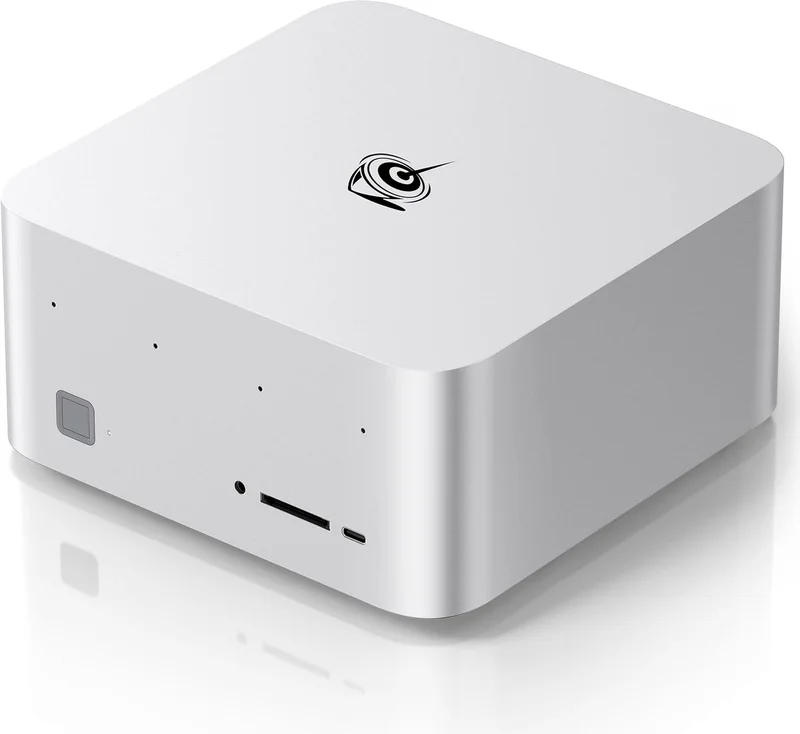
Beelink GTR9 Pro (Ryzen AI Max+ 395, 128GB)
$4,349
- APU: AMD Ryzen AI Max+ 395 (16C/32T, Zen 5)
- GPU: Radeon 8060S (40 CU, RDNA 3.5)
- NPU: 50 TOPS (XDNA 2)
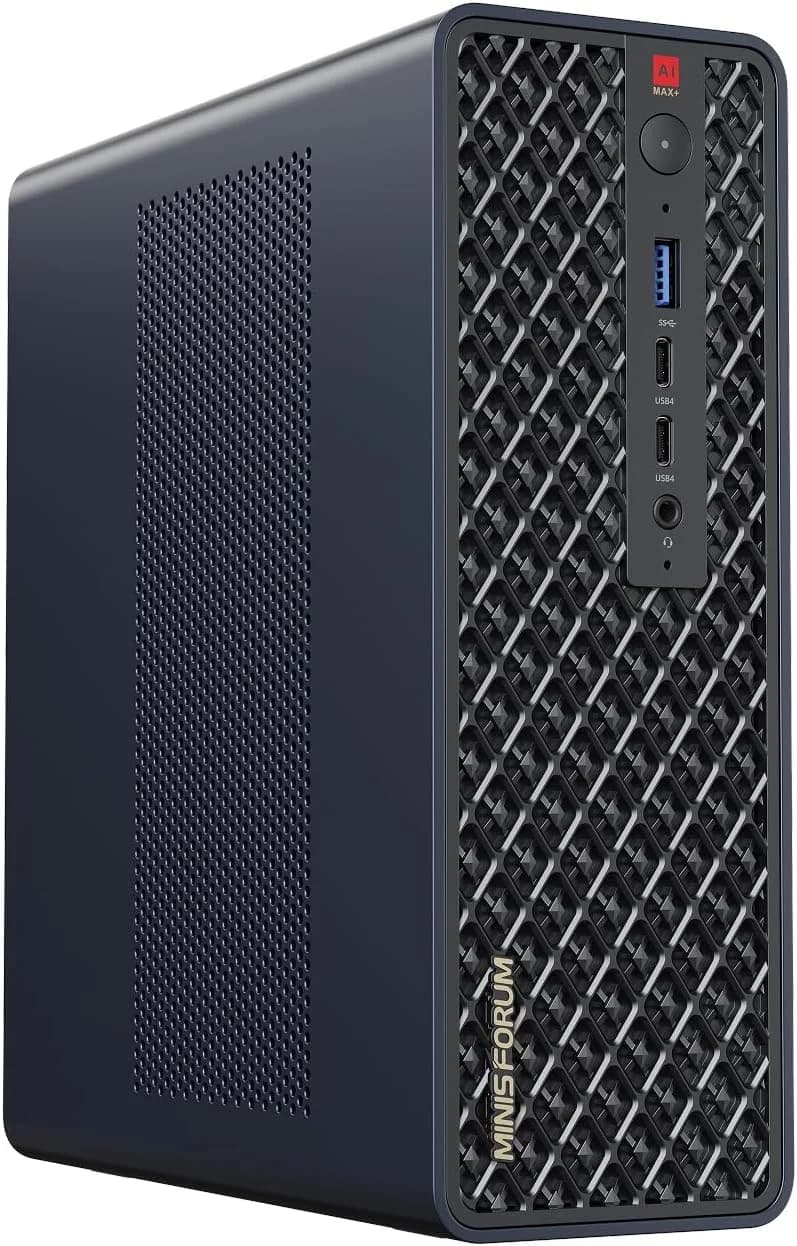
Minisforum MS-S1 Max (Ryzen AI Max+ 395, 128GB)
$3,799
- APU: AMD Ryzen AI Max+ 395 (16C/32T, Zen 5)
- GPU: Radeon 8060S (40 CU, RDNA 3.5)
- NPU: 50 TOPS (XDNA 2)
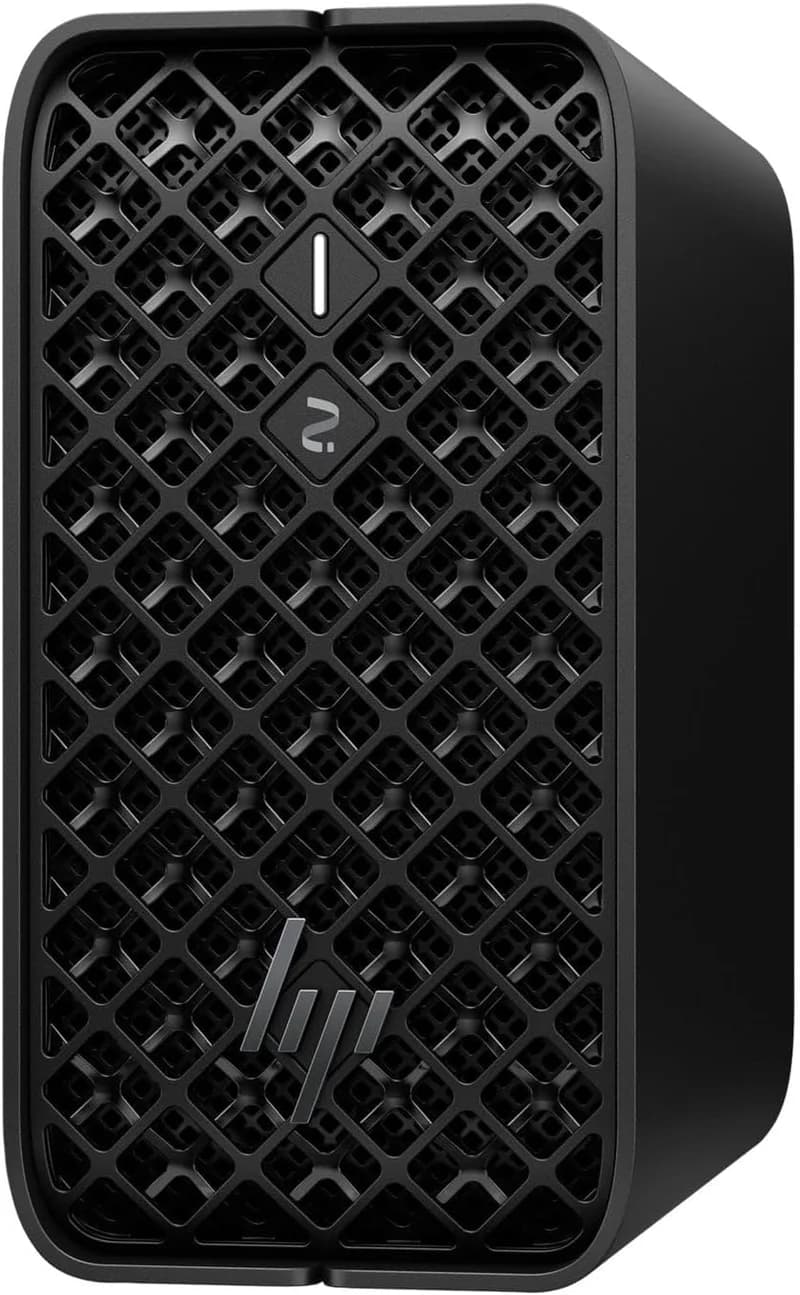
HP Z2 Mini G1a (Ryzen AI Max+ PRO 395, 128GB)
$5,349 – $7,406
- APU: AMD Ryzen AI Max+ PRO 395 (16C/32T, Zen 5, vPro)
- GPU: Radeon 8060S (40 CU, RDNA 3.5)
- NPU: 50 TOPS (XDNA 2)
Framework Desktop (Ryzen AI Max+ 395, 128GB)
$3,449
- APU: AMD Ryzen AI Max+ 395 (16C/32T, Zen 5)
- GPU: Radeon 8060S (40 CU, RDNA 3.5)
- NPU: 50 TOPS (XDNA 2)
Comparisons
Models That Run on These Boxes
Llama 3.3 70B Instruct
Meta's flagship dense chat model — strong general reasoning, coding, and instruction-following that rivals much larger models. The default pick when a single big box has the memory to spare.
LlamaLlama 4 Scout
A mixture-of-experts model — only a fraction of its 109B total parameters are active per token, so it loads like a large model but runs far faster than its size suggests. A natural fit for unified-memory boxes with a long context window.
Qwen3Qwen3 8B
A capable small chat-and-reasoning model that fits comfortably even on budget boxes — a good everyday assistant when you don't need frontier-level depth.
Qwen3Qwen3 14B
The mid-size Qwen3 — noticeably stronger reasoning and coding than the 8B while still fitting mid-range hardware at Q4.
Qwen3Qwen3 32B
Qwen3's large dense model — near-flagship quality that still runs on a single unified-memory box, a strong local alternative to 70B-class models at lower memory cost.
DeepSeek-R1DeepSeek-R1 Distill Qwen 7B
R1's chain-of-thought reasoning distilled into a 7B Qwen base — the lightest way to get R1-style step-by-step reasoning locally, small enough for budget boxes.
DeepSeek-R1DeepSeek-R1 Distill Qwen 14B
The 14B R1 distill — a good balance of reasoning depth and hardware cost, running comfortably on mid-range unified-memory boxes.
DeepSeek-R1DeepSeek-R1 Distill Qwen 32B
The strongest Qwen-based R1 distill — heavy reasoning that still fits a single large-memory box, the sweet spot for local R1-style work.
DeepSeek-R1DeepSeek-R1 Distill Llama 70B
R1's reasoning distilled onto a Llama 70B base — the highest-quality distill, and the one to reach for when the full 671B R1 won't fit (it never does locally).
Gemma 3Gemma 3 4B
Google's smallest current Gemma — tiny memory footprint and multimodal, ideal for the most memory-constrained budget boxes and always-on assistants.
Gemma 3Gemma 3 12B
The mid-size Gemma 3 — solid general-purpose quality with a long context window, fitting mid-range hardware at Q4.
Gemma 3Gemma 3 27B
The largest Gemma 3 — frontier-adjacent quality for a dense open model, comfortably runnable on a single large-memory box.
GPT-OSSGPT-OSS 20B
OpenAI's small open-weight MoE — its 21B total parameters load like a mid-size model, but because only a fraction are active per token it runs fast on modest hardware.
GPT-OSSGPT-OSS 120B
OpenAI's large open-weight MoE — its 117B total parameters fit a single high-memory box, and because only a fraction are active per token it runs far quicker than its total suggests.
PhiPhi-4
Microsoft's 14B model punches well above its size on math and reasoning — a compact, mid-range-friendly pick when you want strong reasoning without a big memory bill.
MistralMistral Small 3.2 24B
Mistral's 24B dense model — fast, capable, and low-latency for its class, sitting neatly between the mid-size and large boxes.
Related Articles
DGX Spark 64GB vs Strix Halo 128GB: NVIDIA's $4,999 Spark Has Half the Memory — Should You Buy It?
On October 2 NVIDIA launched a 64GB DGX Spark at $4,999 and moved the 128GB Spark to $6,950. Every 128GB Strix Halo box in our catalog costs less than the new entry Spark. Here's the price-per-GB math, what actually fits in 64GB, and who should still pay for CUDA.
ReadComparisonMac Studio M5 Max vs Strix Halo: What Apple's September 2026 Refresh Changes for Local LLMs
Apple's M5 Max hits 614 GB/s — roughly 2.9× a Strix Halo box. But the $2,499 headline is a 36GB machine, and getting to 128GB runs a +$600 / +$400 / +$2,000 memory ladder. Here's the arithmetic, including the half that says buy the Mac.
ReadComparisonRTX Spark vs Strix Halo: Buy a 128GB Box Now, or Wait for NVIDIA's October Launch?
NVIDIA's RTX Spark (N1X) ships in October with up to 128GB of unified memory — and NVIDIA's own porting guide puts it at 300 GB/s, not the 600 GB/s everyone is quoting. Here's what that actually changes about the box you buy this week.
ReadGuideHow Much Context Can a 128GB Mini PC Actually Hold? The KV Cache Math Nobody Runs Before Buying
Everyone sizes a unified-memory box against model weights. Almost nobody sizes it against the KV cache — and on a 128K-token agent run, the cache is the number that decides whether the job finishes. Here's the math, box by box, plus the KV-quantization trade that makes long first prompts slower, not faster.
ReadGuide192GB vs 128GB Unified Memory: What the Extra 64GB Actually Buys You
IFA 2026 filled the feeds with 192GB Gorgon Halo mini PCs. Capacity went up 50%; bandwidth went up about 7%. That asymmetry decides the whole purchase — here is the model-by-model list of what only 192GB runs, and why most buyers should still buy 128GB today.
ReadGuideHow Much Unified Memory Do You Actually Need for Local AI? (64GB vs 96GB vs 128GB, 2026)
Unified memory on these boxes is soldered — it is the one spec you cannot change after checkout. Here is what each capacity tier actually runs, what the 64GB tier costs you in usable GPU memory, and why the extra 64GB buys context rather than a bigger model.
ReadGuideCan You Fine-Tune an LLM on a 128GB Mini PC? (And Which Box to Buy in 2026)
LoRA and QLoRA on 20–30B models are practical on 128GB of unified memory; full fine-tunes stop near 12B; dense 70B training doesn't happen on any box in this class. Fine-tuning is the one local-AI workload where the software stack — not memory bandwidth — decides which machine you buy. Here's the capability table, the CUDA tax, and the cloud break-even.
ReadGuideStrix Halo Memory Bandwidth: Why 256 GB/s Isn't 256 GB/s (2026)
AMD's Ryzen AI Max+ 395 is rated 256 GB/s. Real sustained bandwidth is around 215 GB/s — about 84% of spec. Here's where the missing 40 GB/s goes, why 32MB of Infinity Cache doesn't rescue it, and how to turn GB/s into a tokens-per-second estimate before you buy.
ReadGuideBest Mini PC for a Local Coding Agent in 2026 — Why Prefill, Not Tokens/Sec, Decides Your Box
A coding agent re-sends your whole repo context every single turn, which makes it a prefill-bound workload. That flips the buying logic: ~1,700 tok/s prompt processing on a GB10 box vs ~340 tok/s on Strix Halo, while generation is a near-tie. Here's the per-budget verdict, the memory math, and the boxes to skip — with the caveat that the 2026 DRAM spike has narrowed the price gap to about $1,250.
ReadFrequently Asked Questions
What is Strix Halo and why does it matter for local AI?
Strix Halo is AMD's Ryzen AI Max+ 395 — a 16-core Zen 5 APU paired with a Radeon 8060S iGPU and up to 128GB of LPDDR5X unified memory, up to 96GB of which is allocatable as VRAM. That capacity lets a single small box load 70B-class models that no 24–32GB consumer GPU can hold.
How fast is a Strix Halo box for 70B models?
Memory bandwidth is the ceiling. Real-world bandwidth runs roughly 215–273 GB/s depending on the box, so a dense 70B model runs at single-digit tokens per second. Mixture-of-experts (MoE) models activate only a fraction of their weights per token and run far faster.
Which Strix Halo box should I buy?
The GMKtec EVO-X2 is the flagship. The Beelink GTR9 Pro adds dual 10GbE for clustering. The Minisforum MS-S1 Max has the best IO and cooling. The HP Z2 Mini G1a is the premium, business-grade pick with vPro and ECC. The Framework Desktop is the cheapest credible 128GB box at $1,999.
Can I upgrade the memory later?
No. The 128GB LPDDR5X is soldered on every Strix Halo box, so there is no upgrade path — buy the 128GB configuration up front.