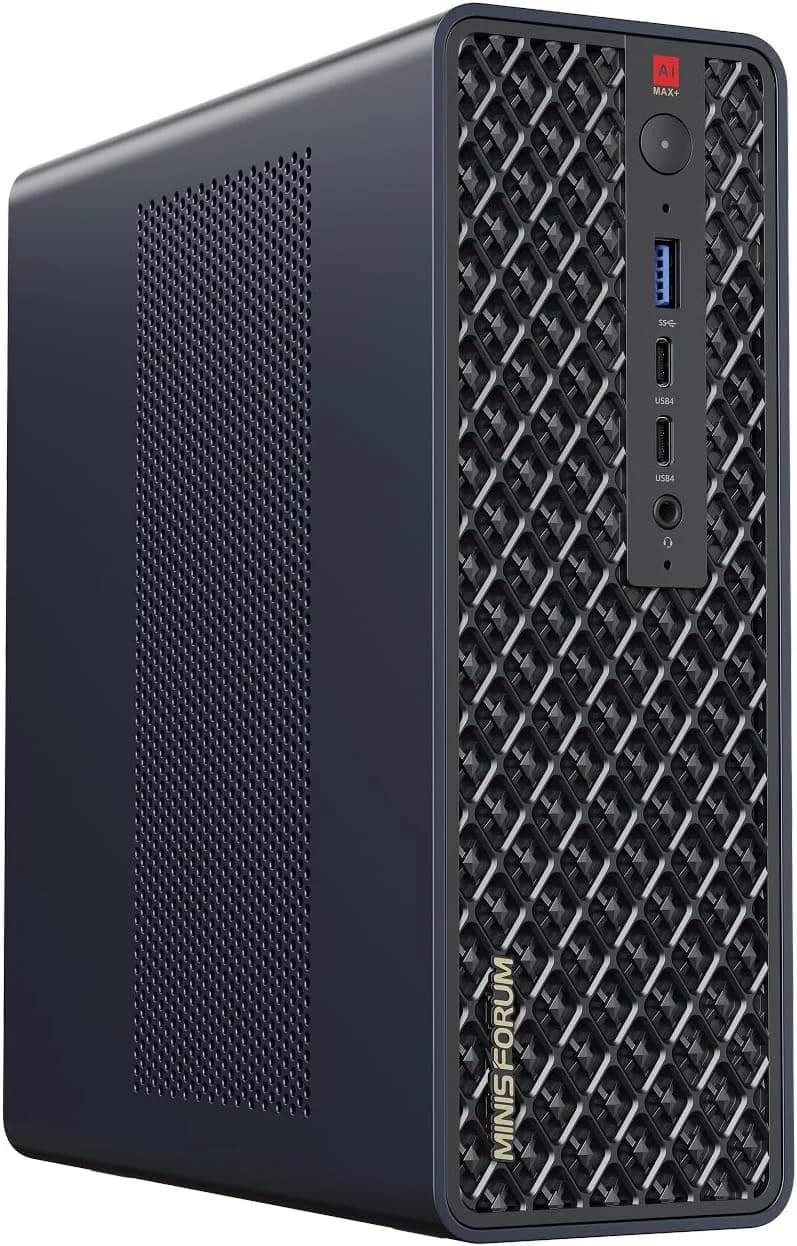
Minisforum MS-S1 Max (Ryzen AI Max+ 395, 128GB)
$3,799
The enthusiast's Strix Halo box. Same 128GB unified memory as the others, but the MS-S1 Max brings the strongest IO and cooling of the group: dual 10GbE, dual USB4 v2 (80Gbps), a PCIe x16 slot, a 320W internal PSU, and a 2U-rack-mount option for multi-box LLM clusters. ServeTheHome called it 'the best Ryzen AI Max mini-PC yet.'
Affiliate links — We earn a commission on qualifying purchases at no cost to you.
Specifications
| APU | AMD Ryzen AI Max+ 395 (16C/32T, Zen 5) |
| GPU | Radeon 8060S (40 CU, RDNA 3.5) |
| NPU | 50 TOPS (XDNA 2) |
| Unified Memory | 128GB LPDDR5X-8000 (up to 96GB GPU-allocatable) |
| Memory Bandwidth | 256 GB/s theoretical (~215 GB/s real) |
| Storage | 2TB NVMe (dual M.2 PCIe 4.0 + PCIe x16 slot) |
| Networking | Dual 10GbE, Wi-Fi 7 |
| I/O | 2× USB4 v2 (80Gbps), HDMI 2.1, 2U-rack option |
Pros
- Best IO of the 128GB boxes — dual 10GbE + dual USB4 v2 + PCIe x16
- 320W PSU + oversized cooler = best sustained inference before throttling
- Rack-mountable for multi-box clusters; ~$700+ cheaper than the HP Z2 Mini
Cons
- Larger than pocket-SFF boxes (not the smallest on a desk)
- Amazon price has swung wildly during the 2026 RAM spike
- Minisforum support/RMA reputation weaker than HP
Related Articles
192GB vs 128GB Unified Memory: What the Extra 64GB Actually Buys You
IFA 2026 filled the feeds with 192GB Gorgon Halo mini PCs. Capacity went up 50%; bandwidth went up about 7%. That asymmetry decides the whole purchase — here is the model-by-model list of what only 192GB runs, and why most buyers should still buy 128GB today.
Ryzen AI Max 400 "Gorgon Halo": Should You Wait, or Buy a 128GB Box Now?
AMD's next Halo chip raises unified memory 50% — to 192GB, with 160GB GPU-allocatable — but bandwidth only rises about 7%, to 273 GB/s. Divide one by the other and the "300B models locally" headline collapses. Here's the arithmetic, and the honest buy-or-wait verdict.
Can You Cluster Two Mini PCs to Run Bigger Local LLMs? (2026 Reality Check)
AMD published a four-node Framework Desktop cluster running a trillion-parameter model, and two DGX Sparks pool 256GB over a single cable. Here's when a second box actually helps, when it makes things slower, and which mini PC to buy if clustering is on your roadmap.
Why Your Local LLM Feels Slow on a Strix Halo Mini PC: The Prefill (Time-to-First-Token) Problem
On a Ryzen AI Max+ 395 box, token generation ties a DGX Spark — but prompt processing (prefill) is ~5× slower (~340 vs ~1,700 tok/s on gpt-oss 120B). On long prompts, that's the delay that makes RAG and coding agents feel sluggish. Here's who it hits, why, and how to fix it.
Related Products
Disclosure: Some links on this page are affiliate links. We may earn a commission if you make a purchase — at no extra cost to you. This helps support our independent reviews.